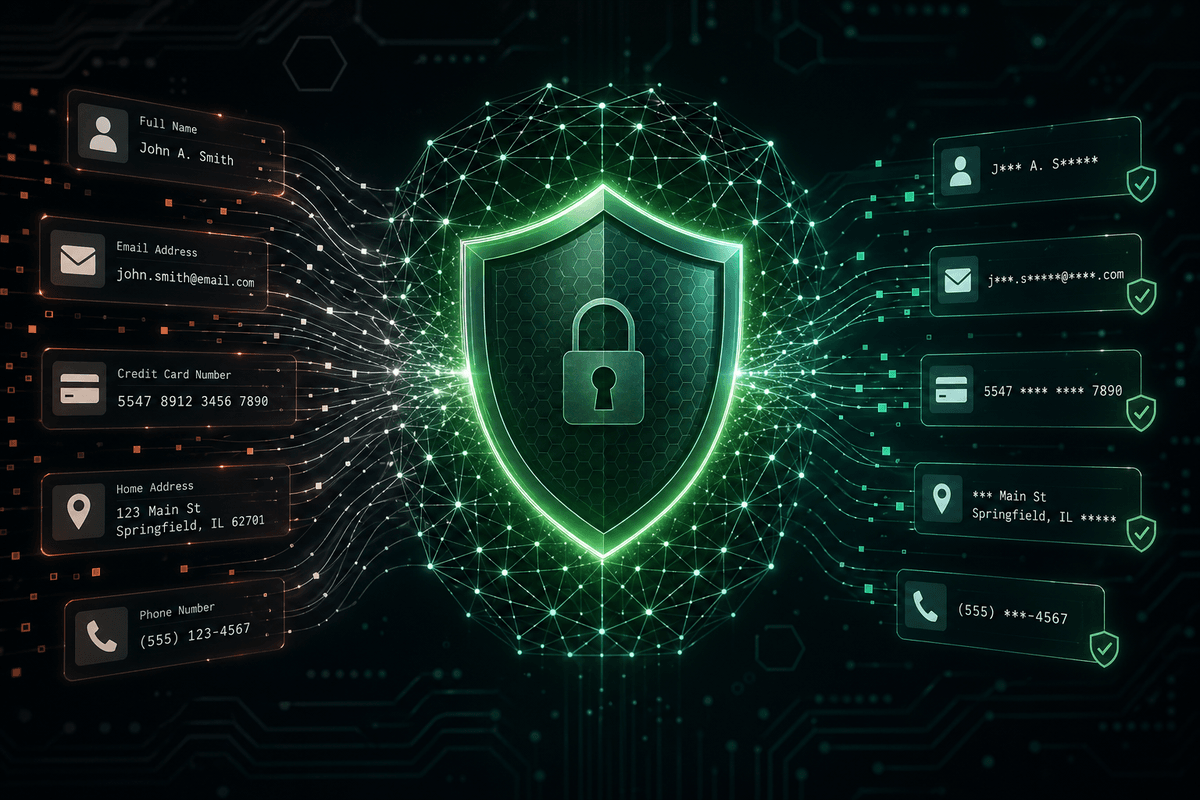
OpenAI’s Privacy Filter detects personal information locally
Privacy Filter detects and redacts personal information in text. OpenAI released the model under Apache 2.0 with downloadable weights.
OpenAI on April 22, 2026, released Privacy Filter, a lightweight open-weight model designed to detect and redact personally identifiable information (PII) in unstructured text1. The model is positioned as a building block for privacy-by-design workflows, enabling developers to sanitize training data, knowledge-base indexes, system logs, and user-facing content without sending sensitive text to third-party APIs1.
Technical Architecture
Privacy Filter is a bidirectional token-classification model with span decoding1. It starts from an autoregressive pretrained checkpoint and replaces the language-modeling head with a token-classification head, then post-trains with a supervised classification objective1. Unlike a generative LLM, it does not produce text token by token; instead, it labels an entire input sequence in a single forward pass and decodes coherent spans using a constrained Viterbi procedure1.
The model has 1.5 billion total parameters with 50 million active parameters1, making it practical to run in production pipelines with modest compute. It supports a 128,000-token context window1, allowing it to process long documents in a single pass.
Detection Taxonomy
The model classifies tokens into an 8-label privacy taxonomy1:
| Label | Coverage |
|---|---|
private_person | Personal identity (names, usernames) |
private_address | Physical addresses |
private_email | Email addresses |
private_phone | Phone numbers |
private_url | Personal URLs |
private_date | Personal dates (birthdays, anniversaries) |
account_number | Financial account numbers, credit cards |
secret | Secrets (passwords, API keys) |
Redaction output replaces detected spans with their label in uppercase (e.g., [PRIVATE_PERSON], [ACCOUNT_NUMBER]) to preserve structural information while removing sensitive content1.
Performance
On the PI**I-Masking-300k benchmark, Privacy Filter achieves an F1 of 96% (precision 94.04%, recall 98.04%)1. After correcting annotation errors in the benchmark, the F1 rises to 97.43% (precision 96.79%, recall 98.08%), placing it at state-of-the-art on this benchmark1.
The model is designed to be domain-adaptable: with a small amount of domain-specific labeled data for fine-tuning, the F1 on a target domain can jump from 54% to 96%1.
Availability and Licensing
Privacy Filter is released under the Apache 2.0 license1. It is available immediately from:
- HuggingFace:
openai/privacy-filter1 - GitHub:
openai/privacy-filter1 - Model Card: a detailed PDF covering architecture, label schema, decoding rules, intended use cases, evaluation setup, and known limitations1
OpenAI reports that it has already deployed a fine-tuned version of Privacy Filter internally within its own privacy workflows1.
Limitations
OpenAI explicitly states that Privacy Filter is not a compliance certification tool and does not replace domain-specific policy review or human oversight in high-sensitivity contexts (legal, healthcare, finance)1. Detection performance depends on the training label schema and decision boundaries; organizations with privacy policies that differ materially from the training distribution may need additional domain evaluation or fine-tuning1.
The model may miss uncommon identifiers or ambiguous personal references, and in low-context settings (especially short text sequences), it may over-redact or under-redact1.
Significance
Privacy Filter represents OpenAI’s effort to contribute practical privacy infrastructure to the open-source community. By releasing a capable, lightweight, Apache-licensed PII detection model, OpenAI lowers the barrier for developers building privacy-respecting AI applications — particularly those who cannot or will not send user data to third-party APIs for sanitization.
The 50M active parameter count is notably small, making the model viable for high-throughput production pipelines where latency and cost matter. The bidirectional architecture (unusual for a model derived from an autoregressive pretrained checkpoint) demonstrates a deliberate design choice: classification accuracy benefits from bidirectional context, even when the base model is autoregressive.
References
Footnotes
Claude Opus 5.5 cuts API prices as GPT-6 Sol launches
Anthropic and OpenAI lowered API prices on the same day. Cache use, reasoning effort, and retries still affect the cost of a completed task.
GPT-5.6's reported access limits and GLM-5.2's open weights
The Information reports a staged GPT-5.6 release with government partner reviews. GLM-5.2 weights are available under an MIT license.
Anthropic’s report on AI-led research and international coordination
Anthropic calls for international coordination on AI-led research while supporting US chip export controls aimed at China. The report also discusses safety-review limits.
Subscribe via RSS
Copy the feed address below and add it to your RSS reader.
Add this address to your RSS reader to receive new articles.